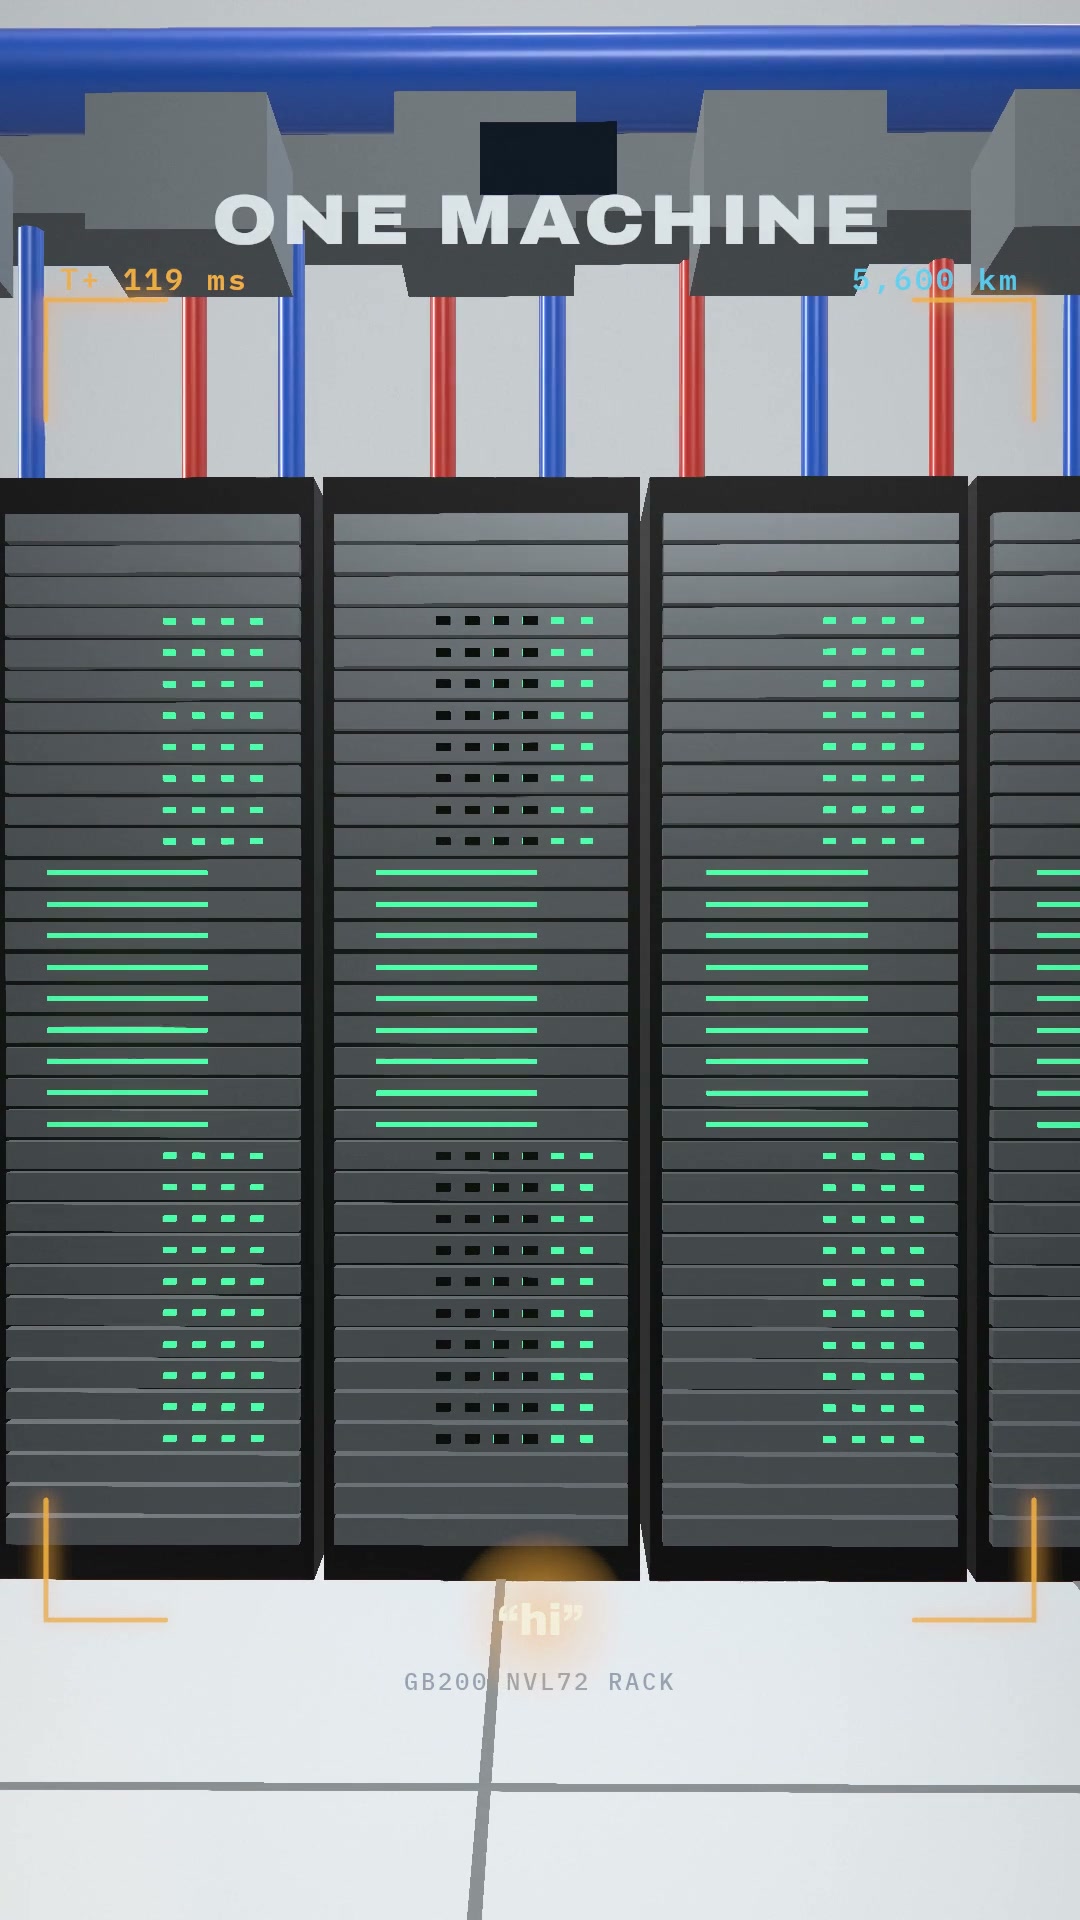
You type "hi" to an LLM.
Search inside any video
SavedThat transcribes your saved videos and lets you search across all of them instantly. Save this video and find any moment.
TL;DR
This video explains the process of how your message to an AI is transmitted and processed, highlighting the technology behind data centers and GPUs.
Chapters
- 0:00Introduction to AI Messaging01
- 0:10Data Transmission Process02
- 0:30Role of Load Balancers03
- 0:50Inside the Data Center04
- 1:10Memory and GPU Processing05
- 1:25Final Output Delivery06
Transcript
You just typed hi to an AI. In the next second, it's going to share a GPU with hundreds of strangers. The moment you hit send, your message gets locked inside an encrypted packet and fired down fiber optic cables, sometimes under an entire ocean. It hits the front door first.
A load balancer catches it, and the gateway checks your key, your limits, and lets you in. Then a router makes a smart choice. It sends you to the exact server that already remembers your chat. Less work? Faster answer. Now you wait in line. Welcome to the data center.
Every rack in here is one machine. 72 GPUs pulling 120 kilowatts. So hot, it's cooled with liquid that comes out at 65 degrees. Your turn. Whatever it already remembers, it skips. The rest, it reads all at once. Every word, in parallel. One giant flash. Then something wild happens. Your memory,
the KV cache, gets shipped across the network to a different set of GPUs, just to write the reply. And here's those strangers. You're one passenger on a packed train. At every step, someone gets off, someone new gets on. Nobody waits. Now the answer comes out one word at a time. And the GPU?
It's barely thinking. It's mostly waiting on memory. Each word races back to your phone the moment it's ready. All of that for one high in under a second.
All of that for one high in under a second.
Are you the creator or rights holder of this video? Request removal of this transcript.
Related Transcripts
 1:03YouTube Shorts
Calibri runs 744B parameter AI on laptop without a GPU using GLM 5.2 #CalibriAI #GLM5 #AIDisruption
Jordan Blake
 1:04Instagram
comment "edit" and i’ll send the breakdown over👇 Day 4 of letting claude code…
Johannes Forseth | AI Systems
 0:57Instagram
110 milliseconds latency.
Values Ventures | Future of Work
 0:41Instagram
Comment Ai for the link.
Jo Mendes
 0:45Instagram
AI can do screen replacements for you 🔥 Comment “AI” for my prompts GPT-6…
Rourke Sefton-Minns
 1:06Instagram
comment "Kallaway" and i’ll send the breakdown over 👇 Day 1 of recreating…
Johannes Forseth | AI Systems
Never lose a moment again
Save videos from YouTube, Instagram, and TikTok. Search everything that was said, and jump to the second.
Start Saving Videos - Free Trial